Compare with a model
On this page
- You need: the toy kit and the AlexNet features from Extract activations (
alexnet_features.npz). - You get: which layers follow a visual property of the images and which follow their category, with RSA and with decoding.
- No brain data needed. To compare the layers with brain patterns, go to Compare with brain data.
What is a model RDM?
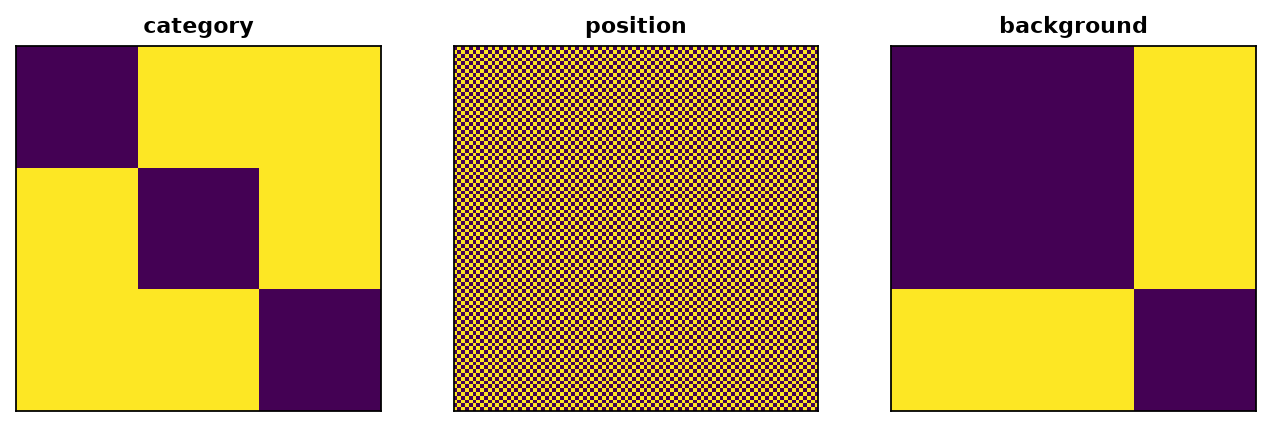
A model RDM writes a hypothesis down as distances between images. A category model says that two images of the same category are similar (distance 0) and two images of different categories are not (distance 1). We test three such models:
- category: critter, food or spooky;
- position: whether the sprite is centred or shifted two pixels, a visual property;
- background: night sky or daylight, another visual property. Only the spooky sprites are out at night, so this model overlaps with category, as visual properties often do with real stimuli.
Comparing a layer's RDM with the models asks which description the layer follows: where things are, what they look like, or what they are.
1. Load the features and build the models
from pathlib import Path

import matplotlib.pyplot as plt
import numpy as np
import pandas as pd
from rsatoolbox.data import Dataset
from rsatoolbox.rdm import calc_rdm, compare, get_categorical_rdm

KIT = Path("dnn-toy-kit")
manifest = pd.read_csv(KIT / "manifest.csv")  # the image order
# One array per layer: images x features (from Extract activations)
dnn = np.load("alexnet_features.npz")
assert (dnn["image_id"] == manifest["image_id"]).all()  # (1)!
layers = ["conv1", "conv2", "conv3", "conv4", "conv5", "fc6", "fc7"]
sprites = manifest["sprite"].to_numpy()

# What each model says about every image
properties = {
    "category": manifest["category"],  # critter, food or spooky
    "position": manifest["variant"].str.endswith("shift").map({True: "shifted", False: "centred"}),  # (2)!
    "background": manifest["category"].map({"spooky": "night", "critter": "day", "food": "day"}),
}
# A model RDM: 0 for two images with the same value, 1 for two images with different values
model_rdms = {}
for name, values in properties.items():
    model_rdms[name] = get_categorical_rdm(pd.factorize(values)[0], category_name=name)  # (3)!
    model_rdms[name].pattern_descriptors["sprite"] = sprites  # (4)!

# One RDM per layer, as on Compare with brain data
layer_rdms = calc_rdm(
    [Dataset(dnn[layer], descriptors={"layer": layer}, obs_descriptors={"sprite": sprites}) for layer in layers],
    method="correlation",
)
- Stop here if the rows of the features are not the images of the manifest, in its order.
- The shifted and the colour-swapped-and-shifted versions are "shifted"; the other two are "centred".
pd.factorizeturns the labels into numbers, and rsatoolbox builds the RDM from them.- Which sprite each image shows. rsatoolbox needs it in section 3, to hold out whole sprites.
Plot the model RDMs
2. One model at a time: Kendall's τA
The simplest test compares each model RDM with each layer RDM on its own:
tau = pd.DataFrame(
    {name: compare(layer_rdms, rdm, method="tau-a").ravel() for name, rdm in model_rdms.items()},  # (1)!
    index=layers,
)
print(tau.round(2))
- Kendall's rank correlation in the variant τA. A model RDM is full of ties, since most pairs are just "same" or "different", and τA does not reward a model for predicting ties (Nili et al., 2014).
Output
Plot the profiles
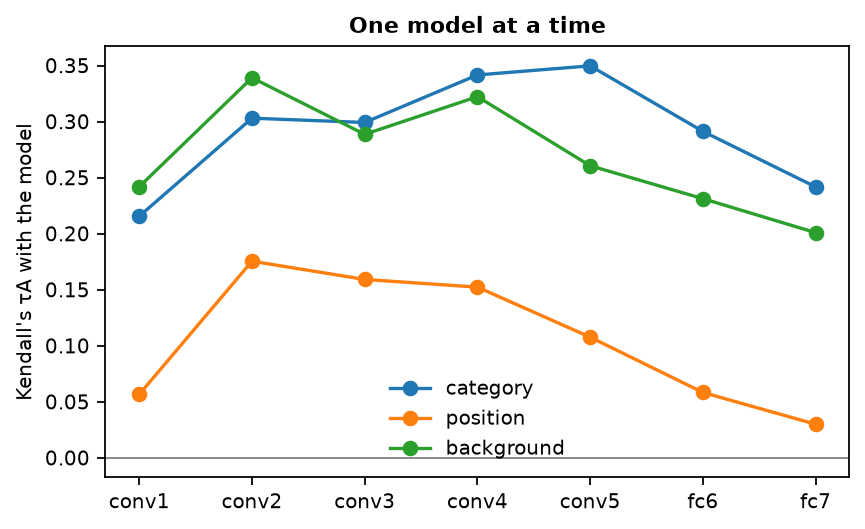
Position shows up in the early convolutional layers: its τA is low at conv1 (0.06), peaks at conv2 (0.18) and falls to 0.03 at fc7, as the network becomes less sensitive to where the sprite sits. Category rises from conv1 (0.22) to conv5 (0.35) and drops a little at the end (fc7, 0.24). Background follows almost the same profile, and in conv1 and conv2 it even matches better than category. Only the spooky sprites are out at night, so the two models overlap, and one model at a time cannot tell them apart.
3. All models together: ridge regression
When models overlap, a layer that follows one of them also matches the other. A regression answers a different question: how much each model contributes once the others are taken into account. rsatoolbox does this with a weighted model, whose weights are fitted to the layer RDM by ridge regression:
from functools import partial

from rsatoolbox.inference import crossval, sets_k_fold
from rsatoolbox.model import ModelFixed, ModelWeighted
from rsatoolbox.model.fitter import fit_regress
from rsatoolbox.rdm import concat

combined = ModelWeighted("all three", concat(list(model_rdms.values())))  # (1)!
combined.default_fitter = partial(fit_regress, ridge_weight=0.1)  # (2)!

# The weight of each model in each layer, fitted on all images
weights = pd.DataFrame(
    [combined.fit(layer_rdms.subset("layer", layer), method="corr") for layer in layers],  # (3)!
    index=layers,
    columns=list(model_rdms),
)
print(weights.round(2))

# How well each model predicts held-out sprites: fit on three quarters of the sprites, test on the rest
candidates = [ModelFixed(name, rdm) for name, rdm in model_rdms.items()] + [combined]
held_out = {}
for layer in layers:
    rdm = layer_rdms.subset("layer", layer)
    train, test, _ = sets_k_fold(rdm, k_rdm=1, k_pattern=4, pattern_descriptor="sprite", random=False)  # (4)!
    result = crossval(candidates, rdm, train, test, method="corr", pattern_descriptor="sprite", calc_noise_ceil=False)
    held_out[layer] = np.nanmean(result.evaluations, axis=(0, 2))  # mean over the four folds
held_out = pd.DataFrame(held_out, index=[model.name for model in candidates]).T
print(held_out.round(2))
- One model whose prediction is a weighted sum of the three model RDMs.
fit_regressestimates the weights by regression, andridge_weightshrinks them towards zero, which keeps them stable when the models are strongly correlated or many. Withmethod="corr"(given tofitandcrossvalbelow), the mean of every RDM is removed first, so the weights describe the pattern of distances rather than their overall level.- The weights are scaled to length 1 within each layer: compare them within a layer, not across layers.
- Four folds of sprites, with all four versions of a sprite on the same side. The fixed models need no fitting; the weighted one is refitted on every training fold and scored on the held-out sprites.
Output
       category  position  background
conv1      0.81      0.31        0.50
conv2      0.69      0.52        0.49
conv3      0.80      0.49        0.35
conv4      0.84      0.43        0.32
conv5      0.95      0.30        0.09
fc6        0.96      0.21        0.18
fc7        0.97      0.13        0.22

       category  position  background  all three
conv1      0.46      0.08        0.41       0.49
conv2      0.60      0.26        0.56       0.69
conv3      0.61      0.25        0.54       0.68
conv4      0.67      0.24        0.55       0.74
conv5      0.69      0.16        0.48       0.71
fc6        0.60      0.04        0.43       0.58
fc7        0.50     -0.01        0.37       0.48
Once category is in the regression, background keeps a large weight only in the early layers (0.50 in conv1, against 0.81 for category) and almost none in conv5 (0.09 against 0.95): there, what looked like a match with the background was the category. Position keeps the profile it had on its own, peaking at conv2 (0.52), because it does not overlap with the other two. On held-out sprites, the combined model predicts the layer RDMs a little better than category alone from conv1 to conv5 (0.74 against 0.67 in conv4, for example), and a little worse in fc6 and fc7 (0.48 against 0.50 in fc7): there, the extra weights fit the training sprites more than they help with new ones. The ridge penalty barely matters here, because three models and 4,560 pairs of images leave little to stabilise.
When to use which.
| One model at a time (τA) | All models together (ridge regression) | |
|---|---|---|
| Question | Does the layer follow this model? | What does each model add beyond the others? |
| Use it when | You test one or a few hypotheses that do not overlap | Your models are correlated, or you want to know which one carries the effect |
| Fitting | None: nothing can be overfitted | Weights are fitted, so judge the model on held-out images, as above |
| Watch out for | Two overlapping models both look good | With many or strongly correlated models, the weights become unstable without the ridge penalty |
For statistics on either, resample images: rsatoolbox.inference.eval_bootstrap_pattern for the fixed models and bootstrap_crossval for the weighted one, both with pattern_descriptor="sprite".
4. Decoding: which layers let you read out each property
Decoding asks the same question in another way: can a linear classifier read the property out of the layer, for sprites it has not seen?
from sklearn.model_selection import StratifiedGroupKFold, cross_val_score
from sklearn.pipeline import make_pipeline
from sklearn.preprocessing import StandardScaler
from sklearn.svm import SVC

sprites = manifest["sprite"].to_numpy()
cv = StratifiedGroupKFold(n_splits=4, shuffle=True, random_state=0)  # (1)!
classifier = make_pipeline(StandardScaler(), SVC(kernel="linear"))  # (2)!
decoding = pd.DataFrame(
    {
        name: [cross_val_score(classifier, dnn[layer], values, groups=sprites, cv=cv).mean() for layer in layers]
        for name, values in properties.items()
        if name in ("category", "position")  # background is just spooky vs the rest
    },
    index=layers,
)
print(decoding.round(2))
- Four folds, each tested on sprites the classifier has not seen, with all four versions of a sprite on the same side.
- The same linear classifier as on Compare with brain data, where a note explains the alternatives.
Output
Plot decoding by layer
fig, ax = plt.subplots(figsize=(6, 3.5))
for name, chance in [("category", 1 / 3), ("position", 1 / 2)]:
    line, = ax.plot(layers, decoding[name], "o-", label=name)
    ax.axhline(chance, color=line.get_color(), ls="--", lw=1)  # chance for this property
ax.set(ylim=(0, 1.05), ylabel="accuracy (new sprites)", title="Decoding by layer (dashed: chance)")
ax.legend(frameon=False)
plt.show()
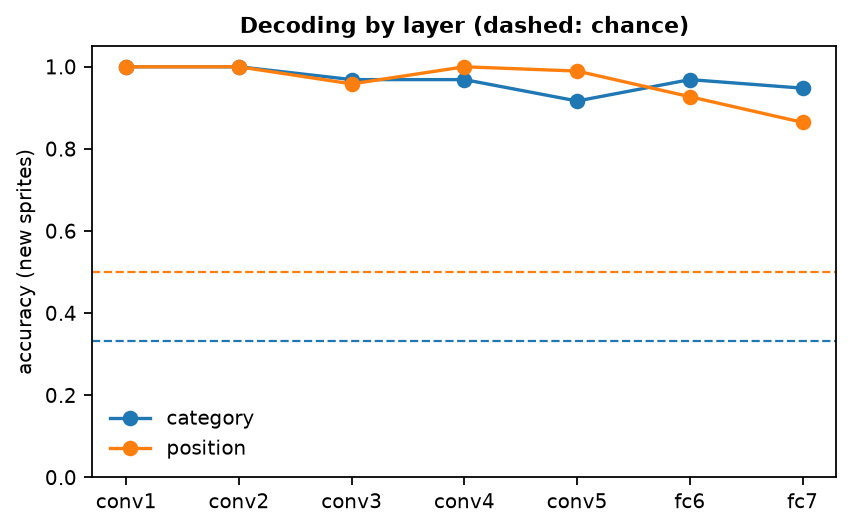
Decoding reads both properties out of almost every layer, position with 86 to 100% (chance 50%) and category with 92 to 100% (chance 33%). Even fc7, whose geometry hardly follows position in the RSA, still tells shifted from centred sprites 86% of the time. Decoding finds any direction in the layer that separates the groups, however small, while RSA asks whether the property shapes the layer's overall geometry. A property can be decodable and still play a minor part in how the layer organises the images.
Good practice
Look for confounds between your models
Two models can make similar predictions. In the toy kit, each category has its own scene, so the category model also describes grass, plates and night skies, a visual property. With real stimuli, build a model RDM for each property that could explain the result (colour, size, background, ...) and check how much they correlate before you interpret one of them.
Several models at once
To ask what each model explains beyond the others, fit them together: rsatoolbox's weighted models (ModelWeighted) or a regression on the RDMs, cross-validated across images. The rsatoolbox documentation has examples.
Where next?
-
The same layers against brain patterns: RSA, decoding and encoding models, with noise ceilings.